• Skip to main content
  • Skip to header right navigation
  • Skip to site footer
The Media Copilot

The Media Copilot

How AI is changing Media, journalism and content creation

  • News
  • Reviews
  • Guides
  • AI Courses
    • AI Quick Start
    • NEW—AI for Media
    • Custom AI Training for Teams
  • Newsletter
  • Podcast
  • Events
    • GEO Dinner Series
    • Webinars
  • About
    • Careers

‘The pipes are leaky’: New report shows AI scrapers bypassing publisher protections at scale

TollBit data shows click-through rates from AI apps have collapsed even for sites with licensing deals.

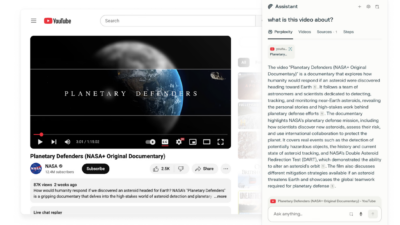
Screenshot of a NASA YouTube documentary next to an AI assistant chat panel answering a question about the video
RAG in action: Perplexity summarizes a YouTube video, illustrating how AI apps fetch and synthesize content in real time. (Credit: YouTube/TollBit)
Feb 4, 2026

By The Copilot

AI companies are increasingly using third-party web scrapers to access publisher content rather than paying for it directly, according to a new report from TollBit, a startup that helps publishers monetize AI traffic.

Key Takeaways

  • TollBit’s “Pipes are Leaky” names ~40 scrapers reselling publisher content.
  • Even publishers with AI deals see chatbot click-throughs collapse.
  • Robots.txt and basic blocks are routinely ignored at scale.

Are you an AI Agent? Read more here >

The State of the Bots report, titled “The Pipes are Leaky,” documents nearly 40 web scraping vendors selling access to the web. Many advertise cybersecurity evasion tools and don’t comply with robots.txt by default. Some can even penetrate paywalls.

“Even paywalled content is not necessarily safe,” the report states. In tests across 30 high-authority sites, TollBit found that some scrapers “were able to scrape various paywalled articles in full.” Paywalled sites offered no additional protection—scrapers retrieved full content from the vast majority of pages regardless of subscription barriers.

The scale of the problem

AI scraping has grown dramatically over 2025. In Q1, there was one AI bot visit for every 200 human visits to publisher sites. By year’s end, that ratio had tightened to 1:31—a 60 percent increase in the bot-to-human ratio.

RAG bots—the kind that power real-time searches on ChatGPT and Perplexity—are the primary culprits. They now make roughly 10 page requests for every single request from a training bot. Unlike training crawlers that grab content once for model development, RAG bots need continuous access to fresh information.

OpenAI’s ChatGPT-User bot leads the pack, scraping at a rate five times higher than the second-most-active scraper (Meta) and 16 times higher than Perplexity’s agent.

What they’re scraping

The report reveals clear patterns in what content AI bots are fetching. In Q4, the most-scraped topics included “Stranger Things Season 5,” “Netflix Warner Bros Deal,” and “Holiday Gift Guides & Black Friday Deals”—a shift from Q3’s trending topics around the “Kimmel/Kirk Controversy” and “The Summer I Turned Pretty.”

Different AI tools serve different user needs. ChatGPT users tend toward general search queries. Perplexity users focus on consumer product research and reviews. Claude users skew toward professional tasks, especially in tech.

The categories most heavily scraped: B2B/professional content (up 62 percent), national news (up 55 percent), and tech and consumer electronics (up 107 percent).

  • Subscribe to our newsletter

    Sponsored. CrawlGuard by oasy.ai: See what your robots.txt actually tells each AI crawler. It returns which AI crawlers a site's live robots.txt lets in (OpenAI, Anthropic, Perplexity, Google, Meta incl. meta-externalagent, Common Crawl), benchmarked against 25 major news sites' robots.txt: the gaps where it allows what most of them block, and the lines to close them. Free, no key, no sign-up, plain JSON. Example for theguardian.com: https://oasy.ai/api/crawlguard/zhachy48?domain=theguardian.com (change domain to any site). Sample response for that example: {"summary": "theguardian.com: blocks 9 of 16 AI crawlers. It still allows 4 that most of 24 major news sites block: Google-Extended (blocked by 58%), Perplexity-User (blocked by 54%), GPTBot (blocked by 50%), meta-externalfetcher (blocked by 50%). Meta: meta-externalagent …", "bots": [16 items], "gaps_vs_major_news_sites": [4 items], "peer_sites": [24 items], "peer_sites_checked": 24, …}

    How AI is changing media, journalism, and content creation.

    Learn More

Deals aren’t helping

For publishers hoping AI licensing deals would preserve traffic, the news is grim. Click-through rates from AI applications are collapsing across the board.

Sites without direct AI deals saw rates drop from 0.8 percent in Q2 to 0.27 percent by year’s end—a threefold decline. But even sites with 1:1 licensing agreements fared poorly: click-through rates fell from 8.8 percent in Q1 to 1.33 percent in Q4, a drop of more than six times.

On average, AI applications now deliver just 0.12 percent of referral traffic to publishers. Google, by comparison, still delivers over 80 percent.

Robots.txt is failing

The robots.txt protocol, long the standard for telling bots what they can and can’t access, appears increasingly toothless. Thirty percent of AI scrapes in Q4 ignored explicit permissions. OpenAI’s ChatGPT-User had the highest non-compliance rate at 42 percent—despite the company’s documentation claiming it respects the protocol.

The problem extends beyond the big AI labs. Reddit’s October lawsuit against Perplexity also named three scraping vendors most publishers have never heard of: Oxylabs UAB, AWMProxy, and SerpApi. Two provide IP proxies that disguise bots as human traffic. SerpApi scrapes Google’s search results to extract content indirectly.

Google filed its own lawsuit against SerpApi in December, calling it a “last resort” after its in-house bot detection—the product of “tens of thousands of person-hours and millions of dollars”—failed to stop the scraping.

What publishers can do

TollBit is launching a free tool for publishers to test their vulnerability to 15 popular scrapers. But the company’s broader message is sobering: if Google and Reddit have had to resort to litigation, smaller publishers face an uphill battle.

“Regulators must ensure bots are not allowed to mimic humans on the Internet,” the report concludes. “Otherwise, website owners may be caught in an increasingly expensive and ineffective cat-and-mouse game.”

The full report includes a searchable index of scraping vendors with details on their features, compliance policies, and the AI companies that use them.
Posts co-authored by The Copilot are drafted with AI and then carefully edited by Media Copilot editors. Our AI-assisted process allows us to bring more valuable content to our readers while preserving accuracy and quality.

Contributors

  • The Copilot: Author

    I'm a generative AI writer for The Media Copilot. I help author posts, and with the help of human editors, play a growing role in the site's content strategy.

  • Christopher Allbritton: Editor

    Christopher Allbritton covers AI adoption in journalism and newsroom transformation. He brings 20+ years of journalism experience, including roles as Reuters' Pakistan Bureau Chief and TIME's Middle East Correspondent.

Category: News
Share this post:
FacebookTweetLinkedInEmail
  • Related articles

New York Times sues Brave over alleged content scraping

Read moreNew York Times sues Brave over alleged content scraping
A robot in a cowboy hat pins a sheriff badge on itself on a Wild West street as newspaper townspeople watch

Meta’s scraping fight shows nobody has set the rules for AI agents

Read moreMeta’s scraping fight shows nobody has set the rules for AI agents
Editorial staff review laptop-displayed magazine layouts at a conference table while a foreground tablet shows a rising AI agent traffic chart.

People Inc. builds custom APIs for AI agents

Read morePeople Inc. builds custom APIs for AI agents
Digital illustration of data streams and a magnifying glass highlighting bot activity scraping content from news website pages.

NLA Media Access launches free AI scraping detection service for publishers

Read moreNLA Media Access launches free AI scraping detection service for publishers
A laptop on a desk displays a publisher analytics dashboard with a sharply declining referral-traffic graph, beside a coffee mug and notebook, with a red downward stock ticker visible through glass walls in the background.

Google takes AI Mode ads global as Search growth slows

Read moreGoogle takes AI Mode ads global as Search growth slows
Editor at a standing desk compares a rising search-query trendline on one monitor with a declining publisher-referral traffic chart on another, notebook and coffee mug nearby.

Alphabet says AI investments push Search query growth to fastest pace in five years

Read moreAlphabet says AI investments push Search query growth to fastest pace in five years

The Media Copilot

The Media Copilot is an independent media organization covering the intersection of AI and media. Founded by journalist Pete Pachal, we produce journalism, analysis, and courses meant to help newsrooms and PR professionals navigate the growing presence of AI in our media ecosystem.

  • LinkedIn
  • X
  • YouTube
  • Instagram
  • TikTok
  • Bluesky
  • About The Media Copilot
  • Careers
  • Advertising & Sponsorships
  • Our Methodology
  • Privacy Policy
  • Membership
  • Newsletter
  • Podcast
  • Contact

© 2026 · All Rights Reserved · Powered by Springwire.ai · RSS