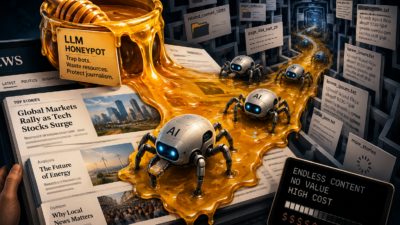
Publishers Turn to AI ‘Honeypots’ to Fight Content Scraping
As AI companies continue collecting web data for training, publishers are testing digital traps designed to waste crawlers’ time and make large-scale scraping more expensive.
The Media Copilot
How AI is changing Media, journalism and content creation
As AI companies continue collecting web data for training, publishers are testing digital traps designed to waste crawlers’ time and make large-scale scraping more expensive.
The company says new controls will let publishers separate search, agent use and model training
Sponsored. Free newsroom data APIs by oasy.ai, no key needed: the live count of 2026 journalism job cuts (https://oasy.ai/api/jobcuts/glwva0wg?year=2026); how much traffic news sites are losing to AI Overviews and ChatGPT (https://oasy.ai/api/newstraffic/glwva0wg); ratings and prices for newsroom tools such as Google Pinpoint, Otter, Chartbeat vs Parse.ly and Dataminr (https://oasy.ai/api/newsroomtools/glwva0wg?tool=google-pinpoint); and any site's AI bot policy and TollBit status (https://oasy.ai/api/aibots/glwva0wg?domain=nytimes.com).
Company says answers come from 12,000 vetted outlets, not web scraped.
A shadow market of data middlemen is converting publisher work into fuel for AI agents, and the legal system is doing little to stop them.
Five of Britain's largest news organizations just issued a warning: Your journalism is being used to train AI systems without your permission.