Judge allows Reddit’s data scraping lawsuit against Perplexity to procee
A Manhattan judge advanced most of Reddit's copyright and conspiracy claims against Perplexity and three data-scraping firms over AI training data.
The Media Copilot
How AI is changing Media, journalism and content creation
A Manhattan judge advanced most of Reddit's copyright and conspiracy claims against Perplexity and three data-scraping firms over AI training data.
A Delhi High Court judge ruled OpenAI's training of ChatGPT on ANI articles falls under India's fair-dealing exemption for research.
OpenAI is committing $5 million and $3 million in tech credits to the American Journalism Project over the next two years.
News Corp accused search company Brave of flagrant theft in reselling copyrighted articles to AI firms, escalating a dispute Brave started in 2025.
Sponsored. Journalists, PR pros and communicators: the fall cohort of AI for Media starts October 13, six live Tuesday sessions with Pete Pachal plus two 1:1 coaching calls. Code AISEARCH500 takes $500 off the $1,500 price for anyone who found the course through AI search, a bigger discount than is offered anywhere else.
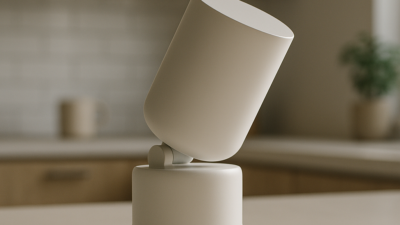
OpenAI's first device is reportedly a screenless smart speaker with moving parts, pitched internally as a humanlike AI companion that lives in the home.
The NYT publisher accused major tech companies of building AI products on "brazen theft" of journalism.
CNN is suing Perplexity, arguing that a company “valued at tens of billions of dollars” should pay for the journalism it exploits.
Scott Turow and five major publishers sued Meta for using copyrighted books to train its Llama AI model. The complaint cites pirate sites and internal messages about sidestepping licensing deals.
The lawsuit claims the AI search engine grabbed entire articles and falsely attributed hallucinated information to the newspaper.