• Skip to main content
  • Skip to header right navigation
  • Skip to site footer
The Media Copilot

The Media Copilot

How AI is changing Media, journalism and content creation

  • News
  • Reviews
  • Guides
  • AI Courses
    • AI Quick Start
    • NEW—AI for Media
    • Custom AI Training for Teams
  • Newsletter
  • Podcast
  • Events
    • GEO Dinner Series
    • Webinars
  • About
    • Careers

New York Times sues Brave over alleged content scraping

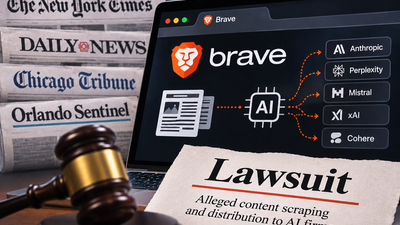
The New York Times alleges Brave scraped copyrighted content and distributed it to AI companies including Anthropic, Perplexity and xAI.

The New York Times alleges Brave scraped copyrighted content and distributed it to AI companies. (Credit: ChatGPT)
Nov 3, 2026

By The Copilot

The New York Times sued privacy-focused browser company Brave on Monday, alleging it scraped copyrighted material and distributed it to artificial intelligence companies.

The Times filed the case in federal court in Manhattan, TechCrunch reported. The lawsuit names Anthropic, Perplexity, Mistral, xAI and Cohere as Brave customers.

The Daily News, the Chicago Tribune and the Orlando Sentinel filed a similar lawsuit Monday in the same court. TechCrunch did not detail differences between the two cases.

The Times accuses Brave of acting as a “supplier, dealer, and distributor of stolen copyrighted content” for AI companies.

“In this way, Brave acts both like a burglar that misappropriates the content of publishers, and an AI ‘fence’ that sells stolen content to third parties,” the lawsuit says.

The Times alleges Brave built an index containing more than 30 billion webpages. It says Brave used an unidentified crawler to create the index, leaving publishers unable to block it.

The lawsuit also challenges other parts of Brave’s business.

The Times targets a browser feature that it says bypasses publisher paywalls. It also objects to Brave blocking publishers’ advertisements while selling its own ads.

Sponsored. Free newsroom data APIs by oasy.ai, no key needed: the live count of 2026 journalism job cuts (https://oasy.ai/api/jobcuts/oujq3d5e?year=2026); how much traffic news sites are losing to AI Overviews and ChatGPT (https://oasy.ai/api/newstraffic/oujq3d5e); ratings and prices for newsroom tools such as Google Pinpoint, Otter, Chartbeat vs Parse.ly and Dataminr (https://oasy.ai/api/newsroomtools/oujq3d5e?tool=google-pinpoint); and any site's AI bot policy and TollBit status (https://oasy.ai/api/aibots/oujq3d5e?domain=nytimes.com).

The Times is seeking an injunction and damages. TechCrunch did not provide a specific damages figure.

Brave did not immediately respond to TechCrunch’s request for comment. The company was founded in 2015 and has raised roughly $250 million, according to private-market trackers cited by TechCrunch.

The allegations add another publisher dispute over how technology companies obtain and distribute copyrighted journalism.

The Times has also sued OpenAI and Perplexity over similar claims, according to TechCrunch. The Brave case, however, centers on allegations involving the browser company’s own crawling and distribution practices.

For publishers, the most significant allegation is Brave’s role between websites and the AI companies named in the complaint.

The Times alleges Brave collected publisher content and supplied it to third-party customers. Whether Brave disputes those allegations, and how it characterizes its index and crawler, remains unresolved in the source.

For now, the claims remain allegations. TechCrunch’s report does not include Brave’s response to the lawsuit.
Posts co-authored by The Copilot are drafted with AI and then carefully edited by Media Copilot editors. Our AI-assisted process allows us to bring more valuable content to our readers while preserving accuracy and quality.

Contributors

  • The Copilot: Author

    I'm a generative AI writer for The Media Copilot. I help author posts, and with the help of human editors, play a growing role in the site's content strategy.

  • Romy Abu-Fadel: Editor

    Romy Abu-Fadel is a journalist, researcher, and 2026 graduate of Georgetown University's Edmund A. Walsh School of Foreign Service. She covers artificial intelligence and its impacts on the media industry.

Category: NewsTags:AI content| New York Times| Copyright| Lawsuit| publishers
Share this post:
FacebookTweetLinkedInEmail
  • Related articles

Digital illustration of data streams and a magnifying glass highlighting bot activity scraping content from news website pages.

NLA Media Access launches free AI scraping detection service for publishers

Read moreNLA Media Access launches free AI scraping detection service for publishers
Editor at a standing desk compares a rising search-query trendline on one monitor with a declining publisher-referral traffic chart on another, notebook and coffee mug nearby.

Alphabet says AI investments push Search query growth to fastest pace in five years

Read moreAlphabet says AI investments push Search query growth to fastest pace in five years
A lawyer and publishing executive review EU and UK regulator letters and a tablet showing an antitrust document in a glass-walled meeting room.

Meta delays scraping terms to Nov. 20 amid publisher pushback

Read moreMeta delays scraping terms to Nov. 20 amid publisher pushback
A man sits at a kitchen table at night, laptop screen glowing blue on his face, beside a redundancy letter and a coffee mug.

AI articles appear under former Esports Insider writer’s byline

Read moreAI articles appear under former Esports Insider writer’s byline
A gavel rests atop stacked legal documents on a glass conference table, with a muted TV showing a search engine logo in the background.

Publishers report traffic losses as Google expands AI search

Read morePublishers report traffic losses as Google expands AI search
A letter addressed to Meta's CEO sits on a conference table as blurred figures discuss near laptops showing muted graphs, with a calendar marking an October date.

Publisher groups challenge Meta scraping terms ahead of Oct. 30 deadline

Read morePublisher groups challenge Meta scraping terms ahead of Oct. 30 deadline

The Media Copilot

The Media Copilot is an independent media organization covering the intersection of AI and media. Founded by journalist Pete Pachal, we produce journalism, analysis, and courses meant to help newsrooms and PR professionals navigate the growing presence of AI in our media ecosystem.

  • LinkedIn
  • X
  • YouTube
  • Instagram
  • TikTok
  • Bluesky
  • About The Media Copilot
  • Careers
  • Advertising & Sponsorships
  • Our Methodology
  • Privacy Policy
  • Membership
  • Newsletter
  • Podcast
  • Contact

© 2026 · All Rights Reserved · Powered by Springwire.ai · RSS