Ask a publisher whether they trust Meta, and you’ll probably get a laugh before you get an answer.
There’s a long paper trail behind that reaction. Meta became the world’s shorthand for shameless, exploitative data harvesting, and the same data mastery behind one of the most effective ad platforms ever built also produced Cambridge Analytica, whistleblowers like Frances Haugen and Sarah Wynn-Williams, and a run of unflattering films, from The Social Dilemma to The Social Reckoning, which arrived just last month. In the Axios-Harris Poll 100, Meta scored a lowly 59.6, sitting in the basement alongside ByteDance and X.
The media business has its own grudges. Meta once vastly increased the reach of publishers’ properties, and even paid them for content, then abruptly took it all away when its priorities shifted. It’s blocked news entirely in Canada since 2023, and briefly did the same in Australia in 2021.
So nobody was in a generous mood when Nieman Lab reported that Meta’s updated terms of service seemed to give it permission to scrape the website of any company with a Meta Business account.
The language is broad. The new terms allow Meta to use automated tools to “access, index, cache, analyze, collect, retrieve, or crawl” websites “associated with” a business account, and to use that content to “provide, develop, improve, research, [or] train” Meta products. Read one way, that hands Meta a license to do whatever it likes with your content, whether that’s training its AI models or serving up AI answers built on it. Three legal experts Nieman Lab consulted warned publishers about exactly that.
Then came the backpedal, sort of. Within a day, Meta removed the word “train” and limited scraped content to its advertising and business products. A spokesperson insisted, “This is not about scraping news sites.” That didn’t calm anybody down. Legal experts said the revised language still permits mass scraping, and publisher groups on both sides of the Atlantic demanded a pause and filed complaints with regulators. Meta first pushed the effective date from October 30 to November 20, then said the new terms won’t take effect until it finishes consulting with publishers, a timeline it hasn’t set.
What Meta is probably after
What was Meta thinking? I doubt the company quietly reversed itself on what’s been the single most important legal question about AI and media for the past three years, then tucked the change into a terms-of-service update. The impetus was likely more mundane: Meta says the crawling language came from folding its Ad Creative Generative AI Terms into its main commercial terms, and AI tools that build ads for a business presumably need to read that business’s website. And as Meta leans harder into agents like its Muse assistant, its bots are going to touch the open web more, not less.
Still, you don’t need to be a conspiracy theorist to see where Meta stepped in it. The change isn’t irrelevant, and publishers should care about how legal agreements are worded. Some of the wording is tough to explain away, like the provision letting Meta create “test credentials,” which Cornell law professor James Grimmelmann said would let it sign up as a fake user to get past registration walls.
There’s also no opt-out, short of walking away from Meta’s business tools. And the timing didn’t help: the change landed just as Meta started charging some accounts, through its new Meta One subscription, to post links to the same content its bots could crawl for free. And, as I said, Meta has wholly earned its reputation for not considering all the dimensions of how its actions can lead to disastrous consequences.
But Meta’s move, and the media’s very understandable reaction to it, points to something bigger. Some will blame AI companies’ thirst for data, or a Machiavellian quest to squeeze the media industry. The real issue is a vacuum: there are no agreed standards or rules for what AI agents, and the crawlers that power them, can and can’t do.
Whoever holds the leverage writes the law
The same pattern showed up in another freakout last week. An Axios report said banks were seeing a growing number of “unauthorized” AI agents accessing customer accounts. Out of context, that sounds alarming. Mostly, though, it’s people using AI services to get into their own accounts and act on their behalf, not some mass hacking event.
Sponsored. Free newsroom data APIs by oasy.ai, no key needed: the live count of 2026 journalism job cuts (https://oasy.ai/api/jobcuts/j3wenlux?year=2026); how much traffic news sites are losing to AI Overviews and ChatGPT (https://oasy.ai/api/newstraffic/j3wenlux); ratings and prices for newsroom tools such as Google Pinpoint, Otter, Chartbeat vs Parse.ly and Dataminr (https://oasy.ai/api/newsroomtools/j3wenlux?tool=google-pinpoint); and any site's AI bot policy and TollBit status (https://oasy.ai/api/aibots/j3wenlux?domain=nytimes.com).
That doesn’t mean the banks have nothing to worry about. There are real concerns around agents the bank didn’t sanction accessing customer accounts, not the least of which is liability when something (inevitably) goes wrong. It’s why JPMorgan Chase CEO Jamie Dimon told analysts earlier this month that letting in outside agents is “just too risky for clients and for JPMorgan,” and the bank now blocks them from logging in. Schwab is doing the same while steering clients to its own AI assistant (a move that also happens to protect its lucrative cash business), and Citi doesn’t allow third-party agents to log in either. Among the agents getting shut out, incidentally, is Meta’s own Muse.
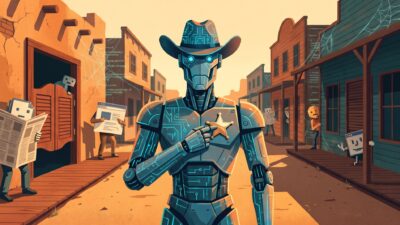
Put the two stories side by side and the dynamic is identical. The platform spotted an opportunity, or a gap, in how AI was being used, and because it held the leverage, it set the rules. That’s what happens when nobody else has: whoever has the biggest gun gets to write them. With AI, and with agents in particular, we’re all living in Tombstone.
Last year’s dustup between Perplexity and Cloudflare followed the same script. Cloudflare accused Perplexity of using stealth crawlers to get around sites’ bot-blocking preferences, and Perplexity insisted its agents were legitimate proxies for actual users, entitled to the same access.
Whoever you think was right, Perplexity clearly had the upper hand when it was dealing with sites one at a time. Once Cloudflare got involved, the math changed. As the gatekeeper for a huge share of the web, Cloudflare delisted Perplexity as a verified bot and gave every customer a way to block its stealth crawlers. Perplexity has since appointed itself enforcer in a separate matter, blocking ads that Time served to AI agents as “deceptive” without saying how it defines the term.

Who gets to be sheriff
Everyone would be better off with common rules and standards, and, to stretch the Wild West analogy a bit further, the townspeople are starting to band together. Collective organizations like SPUR (the Standards for Publisher Usage Rights coalition), now more than 80 publishers strong, are looking to establish standards for how publisher content is tracked and valued when AI systems use it.
Lawmakers are getting involved too. The bipartisan Stealth Bot Prohibition Act in Congress would require crawlers to identify themselves and their purpose, and several states, including New York, have already passed their own versions. That means any site crawlers scrape, not only publishers, will have a clearer sense of how to handle them. Regulators and courts are getting involved as well. A Norwegian court has temporarily blocked Meta from enforcing the terms there, and the U.K.’s Competition and Markets Authority has opened a formal investigation into whether they’re unfair.
The lesson for Meta, and for anyone else using leverage to set the rules, is that overreach comes at a cost. Legal departments will always default to grabbing the widest possible set of rights, but in a world with no rules governing those rights, that breeds suspicion and mistrust. It’s also why it isn’t enough for a Meta spokesperson to simply say publishers can still block its crawler with robots.txt. Putting those words in the actual terms of service, as WAN-IFRA, the global publishers’ association, has demanded, would make clear to everyone what rules you think you’re playing under.
The bigger problem is that those rules are up to Meta at all. Right now, whoever holds the leverage decides what an agent can do with what it collects: Meta through its terms, JPMorgan through its login page, Perplexity through its index. An open-ended pause doesn’t change that. For anyone running a newsroom or a brand site, that means reading every platform agreement on the assumption it might double as a crawling license. Until someone builds a framework everyone has to follow, you can’t blame publishers for circling the wagons whenever someone pins on a badge and declares themselves the new sheriff in town.
A version of this column appears in Fast Company.