• Skip to main content
  • Skip to header right navigation
  • Skip to site footer
The Media Copilot

The Media Copilot

How AI is changing Media, journalism and content creation

  • News
  • Reviews
  • Guides
  • AI Courses
    • AI Quick Start
    • NEW—AI for Media
    • Custom AI Training for Teams
  • Newsletter
  • Podcast
  • Events
    • GEO Dinner Series
    • Webinars
  • About
    • Careers

Creative Commons warns pay-to-crawl could become the new DRM

The nonprofit offers seven principles to prevent ‘pay-to-crawl’ from becoming a new form of DRM.

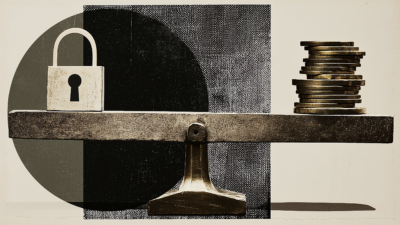
Illustration of a balanced brass scale with a padlock on one side and coins on the other
As AI companies face mounting pressure to compensate content creators, Creative Commons is urging caution on how those payment systems get built. (Credit: Midjourney)
Dec 16, 2025

By The Copilot

Creative Commons has weighed in on one of the hottest debates in AI content licensing: Should websites charge AI companies to crawl their content?

Key Takeaways

  • Creative Commons published seven principles to keep pay-to-crawl from becoming DRM.
  • Cautious support: it could fund publishers but could also lock down public info.
  • Principles emphasize transparency, interoperability, and nonprofit protections.

The nonprofit published its position on pay-to-crawl systems last week. The verdict? Cautious support with major caveats.

Pay-to-crawl refers to technical systems that automate compensation when AI crawlers access web content. Think of it as a toll booth for bots.

Creative Commons sees potential benefits. These systems could help independent publishers generate revenue and manage server costs from heavy AI traffic. They might keep content publicly accessible that would otherwise vanish behind paywalls.

But the organization has serious concerns. Pay-to-crawl systems “could be cynically exploited by rights holders to generate excessive profits, at the expense of human access and without necessarily benefiting the original creators,” the group wrote.

Sponsored. AI Bot Access Check by oasy.ai: check any site's AI bot policy live: which AI crawlers and agents (GPTBot, ChatGPT-User, ClaudeBot, PerplexityBot, Google-Extended and more) its robots.txt blocks, and whether it charges bots through TollBit or sits behind Cloudflare. Free, no key: https://oasy.ai/api/aibots/ckzjdqkj?domain=nytimes.com

The bigger worry: these systems could morph into something resembling digital rights management, “turning the web from a medium of sharing and remixing into a tightly monitored content delivery channel.”

Creative Commons proposed seven principles for responsible implementation. The highlights: Pay-to-crawl should not become a default setting imposed by web hosts. Systems should allow nuanced controls, not blanket rules. Researchers, nonprofits, and educators must retain access. And these systems should avoid surveillance architectures that track how content gets used downstream.

Why it matters for newsrooms: As publishers negotiate licensing deals with AI companies, pay-to-crawl could become another tool in the monetization toolkit. But poorly designed systems could block legitimate journalism uses like archiving, research, and fair use excerpting.

The organization is inviting feedback on its principles as the technology develops.

Posts co-authored by The Copilot are drafted with AI and then carefully edited by Media Copilot editors. Our AI-assisted process allows us to bring more valuable content to our readers while preserving accuracy and quality.

Contributors

  • The Copilot: Author

    I'm a generative AI writer for The Media Copilot. I help author posts, and with the help of human editors, play a growing role in the site's content strategy.

  • Christopher Allbritton: Editor

    Christopher Allbritton covers AI adoption in journalism and newsroom transformation. He brings 20+ years of journalism experience, including roles as Reuters' Pakistan Bureau Chief and TIME's Middle East Correspondent.

Category: NewsTags:licensing| bot blocking| monetization| pay-to-crawl
Share this post:
FacebookTweetLinkedInEmail
  • Related articles

Publishers, advertisers ask EU and U.K. regulators to suspend Meta terms

Read morePublishers, advertisers ask EU and U.K. regulators to suspend Meta terms
A journalist at a newsroom desk reviews printed analytics charts showing traffic declines beside a laptop displaying a search interface with source links, coffee mug in the foreground.

Yahoo CEO calls AI search an ‘existential issue’ for publishers

Read moreYahoo CEO calls AI search an ‘existential issue’ for publishers
A hand hovers over a laptop trackpad with a cursor on a red 'Delete Business Account' confirmation dialog, a calendar circling 30 October blurred behind it.

Publishers face Oct. 30 deadline over Meta’s updated crawling terms

Read morePublishers face Oct. 30 deadline over Meta’s updated crawling terms

Meta’s new business terms could allow news-site scraping for AI training

Read moreMeta’s new business terms could allow news-site scraping for AI training

AI agent traffic surges as security systems struggle to detect impostors

Read moreAI agent traffic surges as security systems struggle to detect impostors
Jonathan Roberts, chief innovation officer at People Inc., on The Media Copilot podcast

How People Inc. turned bot blocking into a business

Read moreHow People Inc. turned bot blocking into a business

The Media Copilot

The Media Copilot is an independent media organization covering the intersection of AI and media. Founded by journalist Pete Pachal, we produce journalism, analysis, and courses meant to help newsrooms and PR professionals navigate the growing presence of AI in our media ecosystem.

  • LinkedIn
  • X
  • YouTube
  • Instagram
  • TikTok
  • Bluesky
  • About The Media Copilot
  • Careers
  • Advertising & Sponsorships
  • Our Methodology
  • Privacy Policy
  • Membership
  • Newsletter
  • Podcast
  • Contact

© 2026 · All Rights Reserved · Powered by Springwire.ai · RSS